
12 June 2017 (first preprint posted) / Americas
The Transformer organizes sequence modelling around attention
Attention Is All You Need introduced the Transformer, using attention to relate sequence elements and testing the architecture on machine translation.
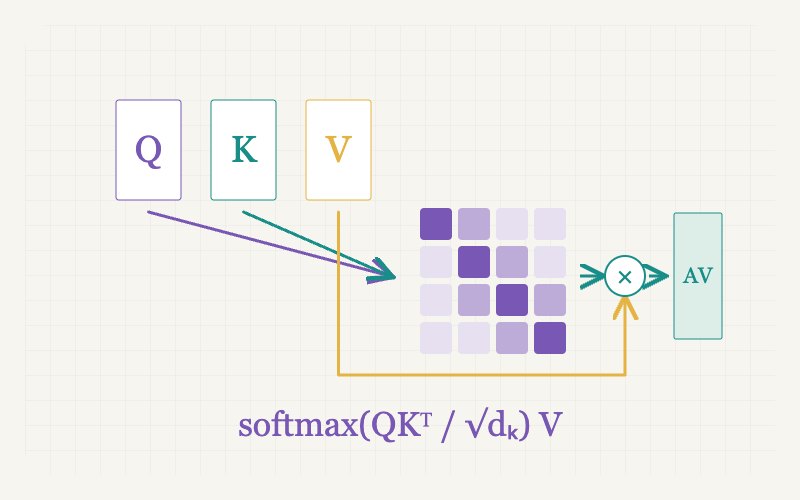
Image unavailable. The caption and source are still available.
The story
The paper by Vaswani and seven co-authors combined attention, positional encoding and feed-forward layers in an encoder–decoder architecture without recurrence or convolution as its sequence-modelling backbone. Its experiments focused on machine translation, not today’s chat applications or proof of general intelligence. Attention had earlier histories, while later pretraining, datasets and architectural changes were further developments. One paper therefore does not represent the origin of all artificial intelligence.
Connections and context
The architecture built on neural-network training and attention research. Data, computing hardware, optimization and evaluation also shaped its later uses; a network diagram alone cannot explain that development.
Dates and precision
12 June 2017 (first preprint posted) Documented date
Positioned by the documented year, month or day. Missing precision is not inferred.
Representative map location
Mountain View and a Google research collaboration
Mountain View represents Google’s research environment, not an exact experiment address supplied by the paper. Affiliations include Google Brain and Google Research.
Representative coordinates · 37.422°, -122.084°
A marker identifies one representative place, such as a manuscript collection, laboratory or observing site. It does not mean the work happened only there, or assign a shared discovery to one country.
Bibliography
- Vaswani and co-authors: Attention Is All You Need, first preprint
- Google Research: Attention Is All You Need
References are listed as plain bibliography titles. They support particular facts or context; a reference does not certify every interpretation in a story.